Your tests pass. Corral finds the bugs they miss — and hands you the tests that catch them.
It plants faults in your code and runs your own test suite against each one. For survivors, it attempts new tests and keeps only execution-demonstrated proofs: tests that fail on the fault and pass on your unmodified code. Not every survivor gets proven; the tests it returns still need your review.
The bug our tests missed internal/certify/certify.go
    if err := json.Unmarshal(payload, &stmt); err != nil {
-     return nil, false, nil
+     return stmt, true, nil
    }
VerifyDSSE accepted a signed envelope whose payload was not valid JSON, instead of rejecting it.
With this bug in, our own tests still passed.
The test corral wrote (gemini-3.6-flash)
func TestVerifyDSSEInvalidJSONPayloadFails(t *testing.T) {
  pub, priv, err := ed25519.GenerateKey(rand.Reader)
  if err != nil {
    t.Fatalf("GenerateKey: %v", err)
  }

  sv := &ed25519SigVerifier{priv: priv, keyID: "corral-test"}
  es, err := dsse.NewEnvelopeSigner(sv)
  if err != nil {
    t.Fatalf("NewEnvelopeSigner: %v", err)
  }

  invalidPayload := []byte("{this is not valid json")
  env, err := es.SignPayload(context.Background(), intotoPayloadType, invalidPayload)
  if err != nil {
    t.Fatalf("SignPayload: %v", err)
  }

  envelopeBytes, err := json.Marshal(env)
  if err != nil {
    t.Fatalf("json.Marshal envelope: %v", err)
  }

  _, ok, err := VerifyDSSE(envelopeBytes, pub)
  if err != nil {
    t.Fatalf("VerifyDSSE unexpected error: %v", err)
  }
  if ok {
    t.Fatal("VerifyDSSE must return ok=false when envelope payload is not valid JSON")
  }
}
Fails with the bug in. Passes on the real code.
78 bugs planted · 35 slipped past our tests · 30 now have a test that catches them. We merged this one the next day (#210).
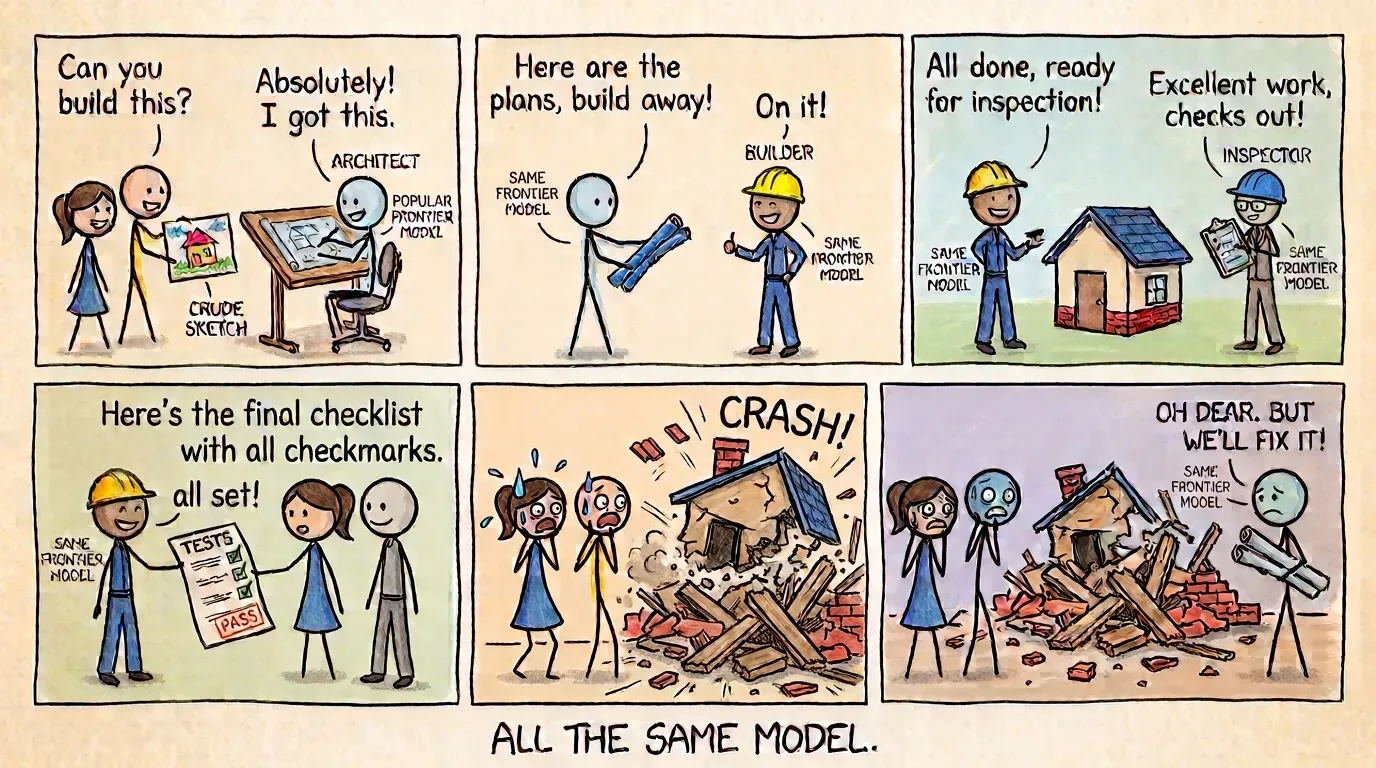
Why: everyone is building build harnesses. Corral is the one that refuses to build.
Nemo iudex in causa sua — no one may be judge in their own cause.
Would you trust your house if the same person architected it, built it, inspected it, and certified it? Corral is an auditing engine. It judges code it did not write — by execution and by adversary — onto a signed, tamper-evident record. Accountability, paper trail, analysis, certification: everything but building.
Two extensions carry the rule: certify breaks your code on purpose and runs your own tests against every fault; review hands your code to a model that has never seen it and makes every claim prove itself by script, with a second model arguing the other side. Both write hash-linked entries to a ledger directory in your repository, signed when a certify key is configured. Keep that directory on its own corral/ledger branch and, run as a GitHub Action, GitHub becomes the record that any DuckDB can read.
Below is a real run, replaying now: a decorrelated herd put internal/certify/certify.go to its own tests — gemini-3.6-flash planted 78 faults, and the project's own test suite was run against every one of them in a sandbox. No model graded anything: the suite's exit code decided, and it caught 43, missed 35. A different model, gemini-3.7-flash, reviewed the run alongside it — the critic advises and is never allowed to decide. Signed NEEDS-REVIEW, and the herd handed back a test that catches the gap.
We ran our own gate on our own signing code and published the result: NEEDS-REVIEW. 43 of 78 planted faults killed, 35 survived — and the writer handed back tests proving 30 of them catchable. The corrective-retry loop is visible mid-tape: an authored test failed on clean code and was reissued with the failure fed back.
internal/certify/certify.go43/78 faults caught · 55% kill-rategemini-3.6-flash + gemini-3.7-flashWhat you just watched — the full breakdown
What was tested
- Code under audit
internal/certify/certify.go- The goal it must satisfy
- “the signed audit statement is tamper-evident: any change to the verdict, the subject hashes, or the model names must break the ed25519 DSSE signature, and verification must fail closed”
- Graded by
internal/certify/certify_test.go— the project’s own tests
The decorrelated herd
- Planted the faults
- gemini-3.6-flash
- Wrote exposing tests
- gemini-3.6-flash
- Critiqued the suite different model
- gemini-3.7-flash
What happened, in a jail
- Planted 78 goal-violating mutants across the file.
- Ran the developer’s own suite against every one — it killed 43 of 78 (a 55% kill-rate), measured by execution, not asserted.
- Verdict: NEEDS-REVIEW — signed with the local certify key of the machine that ran it, and the herd handed back a compiling test that kills the gap.
What it does — and doesn’t — claim
- 35 survivors disclosed, unadjudicated: an injected mutant the suite didn’t kill — a real untested edge, or an equivalent mutant nothing can catch. Corral hands it to a human to judge; it doesn’t rule the code buggy.
Certified by execution — run in a jail, not taken on a model's wordDecorrelated — the judge is never the author; enforced, not hopedSigned & offline-verifiable — tamper-evident, human-gated
Corral is the reactive audit you put downstream of every AI coding tool — agnostic to whoever, or whatever, wrote the change. It mutates the code to plant real faults and checks whether the developer's own tests catch them — a test that catches nothing proves nothing — while a decorrelated critic, a different model than the one that wrote the exposing test, reads the suite for theater. The verdict is measured by execution in a jail, never taken on a model's word. Any model, local 7B to frontier, mixed in one run. Human-gated and fail-closed; every run recorded into a hash-linked record, signed when a certify key is configured. The adversarial pool is the product: certify --local, certify --repo and the GitHub Action all run it. What is optional is the brain daemon, which no audit needs.
Free, source-available, and getting better with every run — a star helps other people find it.
Watch it work — two real runs
Both extensions, pointed at flask at 36e4a824 — a library we did not write — and both ending on the same frame: corral's own record, verified from a fresh clone. These are recordings of actual runs. The pipeline applies pacing and captions and nothing else; the first caption of each video says exactly what was applied.
certify — 56 seconds
Goals derived from app.py, then 40 deliberate faults planted in it and flask's own test suite run against every one of them in a jail. It caught 29 and slept through 11 — a kill rate of 0.72. A second model then wrote a test for each survivor and ran it alone against its fault: 10 of the 11 became demonstrated gaps, bugs the suite misses with the test that catches them attached. Ends with the signed verdict entered into Sigstore's public log (index 2759598612, the one you watch being issued) and the chain verified.
review — 84 seconds
Claude Code reviews src/flask/sessions.py cold and Codex argues the other side. Five claims come back — and the three the reviewer declared reproduced had scripts that did not demonstrate them, so corral demoted its own reviewer on the record: 0 reproduced, 5 standing as read. Then a person checks the top claim by hand — on an app with no secret key, session["a"]=1 raises the documented error but session |= {"a": 1} is silently accepted and the write dropped — and rules it real. The defect stood; the overclaim did not.
One run each, not a grade. Faults are generated fresh every time, so the same file scores differently on different runs — six scans of flask's cli.py on one day ranged from 0.375 to 0.525 (the data behind the warehouse page). That spread is the reason to inspect each proven gap as a specific recorded fault/test pair rather than read a kill rate as a stable grade. Discovery in a fresh run can vary too: it may find different gaps or prove none, so a proven-gap gate is not guaranteed to return the same result. Both runs above are entries on the public branch; query them and you will get these numbers.
Both close on the same frame: a fresh clone of corral/ledger, corral ledger verify, one SELECT over the entries, a push to MotherDuck, and the seats ranked by the record they left. How it works →
It runs on your pull requests
A principle nobody enforces is a slogan. The way corral enforces this one is a GitHub Action: it installs itself, audits only the files a pull request actually touched, and writes the verdict to the run page verbatim — including the lines that say what a number does not mean. One job, and there is no corral for you to install (the Action builds it with the runner's Go toolchain, which ubuntu-latest already has; a self-hosted runner needs actions/setup-go first). corral has no default models, so the job names every seat:
# one job of a workflow on: pull_request, runs-on: ubuntu-latest
permissions:
  id-token: write             # these three are required by attest
  attestations: write
  contents: read
steps:
  - uses: actions/checkout@v4
    with:
      fetch-depth: 0          # required — the diff needs a merge base
  - uses: pdbethke/corralai@v1.0.0-rc.28
    with:
      test-command: "go test ./..."
      derive-model: claude-sonnet-5
      writer-model: claude-sonnet-5
      mutant-model: claude-sonnet-5
      critic-model: claude-haiku-4-5    # must differ from the writer; "off" drops it
      anthropic-key: ${{ secrets.ANTHROPIC_API_KEY }}
      max-proven-missed: "0"  # fail on a DEMONSTRATED gap
      attest: "true"          # publish a receipt anyone can verify
max-proven-missed rather than a kill-rate threshold, and the difference matters. A kill rate is a proportion of freshly generated faults, so it moves between runs on code nobody touched — we have watched an unchanged file score 0.375 and then 0.525, and a deliberately weakened suite score higher than it had a moment earlier. Set a bar near a healthy value and it reddens good work with nothing to act on. A proven gap is a survivor the herd then killed with a test it wrote and ran — a specific planted fault your suite misses, with a test shown to catch it. It is a gap in the tests, not a bug found in your code, and a person still decides whether the test belongs. So a max-proven-missed gate fails only with a concrete fault and test in hand. It does not catch everything: a fresh run regenerates its faults, so discovery can vary even on unchanged code, and a fresh run can miss a gap an earlier run found. The recorded fault and test stay inspectable; to compare test changes against the same faults, replay them locally with corral certify --mutants (the Action has no input for that).
attest publishes the verdict as a signed in-toto statement through GitHub's attestation API, keyless, chained to the repository and workflow rather than to a key on a disposable runner. A reviewer verifies it without trusting the log, or you:
gh attestation verify corral-audit-statement.json --repo <owner>/<repo>It is written before the gate's exit code is honoured, so a failing audit still leaves a receipt. A verdict you only keep when it flatters you is not evidence.
What it said about this repository
We pointed it at the file that starts our own program, cmd/corral/main.go, as a gated check on a real commit. It planted 40 deliberate faults. Our suite caught 10 and slept through 30 — a kill rate of 0.25. Then the test-writer authored a test we hadn't written and used it to kill one of those survivors, so that gap is demonstrated rather than alleged. The whole run took 11m12s on a 2-core hosted runner.
That is a bad number, published by the tool that produced it, on a run we could not quietly not-publish. A gate its own author can talk his way past is furniture.
Scoped to the diff, on purpose
An audit costs roughly (mutants × your suite's whole runtime) per file — it scales with how long your tests take and how many files the PR touched, not with the size of the change. So the default is the PR's diff, top bounds how many files one run can spend on, and a whole-repo scan is something you opt into deliberately.
Teeth are opt-in, and per file
A low kill rate alone does not fail a graded scan unless you set min-kill-rate. Set it and any single file below the threshold fails the run; a well-tested file elsewhere in the PR cannot average out a weak one. max-proven-missed is a separate gate on demonstrated test gaps; other execution failures can also fail the run. The thresholds are the operator's.
It won't spend your money on a stranger
The bill lands on the repository that runs the workflow — your runner minutes, your API key. GitHub withholds secrets from fork pull requests: without a job guard they fail for want of a key, rather than skipping. The full workflow in the docs adds a same-repository and audit-label guard; the job excerpt above does not. Add that guard if you want paid runs to require an explicit label. Reaching for pull_request_target to "fix" that would run a contributor's code with your secrets.
And the runner stops forgetting
A CI runner is a throwaway machine: it boots, it measures your code, it is destroyed. The usual way to keep what it learned is to stand up a database — a server, a schema, credentials in CI, a bill — to hold what is really just an append-only list of small facts. Corral doesn't stand anything up. Every verdict is an entry in a ledger directory in your own repository (.corral/ledger by default). Make that directory a worktree of an orphan branch, corral/ledger, and the record shares no history with main, never appears in your diffs, and lives somewhere every runner already has credentials for. In CI, the Action's ledger input names the directory, and your workflow checks the branch out before the audit step and commits it back after (the recipe). GitHub stops being just CI and becomes the record.
DuckDB reads the entries as they are
Entries are gzipped JSON, so the record is in an analytical engine from the first entry: no server, no schema to adopt. Copy the branch's files out without touching your checkout, and point any DuckDB at them:
git fetch origin corral/ledger
mkdir -p /tmp/ledger && git archive origin/corral/ledger | tar -x -C /tmp/ledger

-- then, in duckdb:
SELECT coalesce(kind, 'scan') AS kind, count(*) AS entries
FROM read_json_auto('/tmp/ledger/scans/*.json.gz')
GROUP BY 1 ORDER BY 2 DESC;
An audit's entry has no kind field, hence the coalesce. Any DuckDB client runs it: the CLI, Python, R. Then the questions a single run can never answer are one GROUP BY each: which files have been weak across every scan, which model catches bugs in which language, what an audit costs per file, whose review claims held once execution checked them.
Rekor witnesses it, so it isn't our word
Signing proves integrity under a public key you trust. It does not prove that the measurement or the signer's claims are true. --transparency adds an external witness: it uploads the signed statement to Sigstore's Rekor, a public append-only log run by people with no stake in the audit, and prints the receipt, and records it on the ledger entry. The flask audit on corral's own branch carries index 2759598612 — read it off the entry, fetch it from Sigstore, and check it matches, without asking us for anything.
The entry is public and permanent: once logged it cannot be removed or edited, by anyone, including you. It carries the verdict — repo, commit, paths, kill rates, the models in each role — and never your source. And it fails open: an unreachable log prints one line and leaves the verdict untouched. A witness, not a gate.
Verify one yourself →The next run reads it
The branch is checked out before the audit, so a fresh machine arrives holding everything the repository has learned about itself. Faults already planted on a file's exact bytes become the generator's prior, so it plants somewhere new instead of re-sitting the same exam. A verdict for a file whose bytes haven't changed is reused, and marked reused rather than re-billed. The review planner knows which scopes were covered and which have changed since. Every verdict says whether it was primed this way.
How it works →Tamper-evident, not immutable
Each entry carries the hash of the one before it, and is signed with your certify key when one is configured. Edit a signed entry and its signature breaks for anyone without the key, but whoever holds the key can rewrite and re-sign the whole chain, and ledger verify reports an entry whose signature was stripped as unsigned: a note, not a failure. An unsigned entry has no signer authenticity. A hash alone can be recomputed, so trust comes from a signature or an external anchor, not from the hash stored beside the content. Remove an interior entry and the next entry's link breaks. Remove the tail and the remaining chain is still valid: detecting that truncation needs an external record of the expected head. The ledger owner can delete files; verification is not a guarantee of completeness. On a runner with no key, the recipe attests the entry file itself with GitHub's keyless attestation instead. corral ledger verify walks the chain from a clean checkout; pass a trusted public key to check its signatures. Corral's supported correction path does not edit an entry in place: a wrong entry is retracted by a later entry that says so, and every reader leaves it out.
MotherDuck, when one repo isn't enough
The branch is one repository's record. corral ledger push appends the same entries to a warehouse you own — a plain DuckDB file, or MotherDuck for the view across every repository that pushes. Rows are append-only, because overwriting is how a trend is lost. There is no hosted tier and nothing is collected: your key, your runner, your warehouse. Any DuckDB works, so MotherDuck is a destination rather than a requirement.
It travels with the repository
Fork it, mirror it, move to a self-hosted GitLab or Gitea, hand it to an auditor — the record goes along, because it is the repository. Each entry also names the audited party: author, committer and co-author trailers, so the record says who wrote the change beside who judged it. A person and an agent are named the same way.
On an internal forge →Corral's own record is public at corral/ledger— audits, cold reviews, and the human rulings on them, in a branch you can read without disturbing your own checkout.
How the gate works
Point corral at a code change and the tests that are supposed to cover it. A decorrelated herd of models plants goal-violating faults in the code and runs your tests against each one in the selected execution substrate — measuring the kill rate by execution, never by a self-report. A different model reads the suite cold and critiques it; the writer attempts to author a test for each survivor. A proof is not guaranteed: only tests that pass on the unmodified code and fail on a survivor count. What comes out is a recorded verdict: certified, or needs-review. No one may be judge in their own cause.
change + its tests
  │
  ▼
[mutant-generator] plants goal-violating faults in the code
  │ each fault ↓
  ▼
run YOUR tests against each fault ──► kill-rate (never a self-report)
  │
  ├── faults your tests killed        → covered
  └── survivors (a fault slipped past) → [test-writer] attempts a killing test
                                          keep only execution-demonstrated proofs
  │
  ▼
[test-critic — a DIFFERENT model reads the suite cold]
  │
  ▼
RECORDED VERDICT ─ certified (kill-rate clears the bar, the writer neither
               │                failed nor wrote an unsound test)
               └─ needs-review (below the bar, a writer failure, or an exam too
                                small to judge — a human adjudicates)
Decorrelated by construction
Reusing one model in every role risks correlated blind spots. A cold run of the same model can still find something an earlier run missed; different model names or vendors do not guarantee independence. Corral holds one pair apart by rule: CheckDecorrelation refuses a run where the critic and the test-writer are the same model. The fault-planter and the writer may share a model, and a run whose seats all come from one vendor is allowed — the verdict says so ("every graded seat is …") rather than refusing it. Each role can be pointed at a different vendor, so a Gemini fault-planter with a Claude critic is one run. Mix cheap local models with frontier ones: bring anything OpenAI-compatible, or a local model, on your own key — no vendor lock-in.
And decorrelate from whoever wrote the code. corral keeps the critic apart from the writer; it cannot see the fourth participant — the model that authored the file under audit. If that was Claude and you audit with Claude, the lineage that wrote the code is planting the faults and grading the tests for it. Point the roles at a different vendor than your code came from.
Multi-model herds →Certified by execution, not by a vibe
A suite's grade isn't an opinion. The kill rate is mutation testing, measured by execution on your machine or runner: your real command — go test, pytest, npm test, cargo test, anything — is run against each planted fault inside a sandbox by default (on the host with --substrate workspace), and the exit codes decide what died. A model never tells us it did well; a test that claims to catch a bug has to actually catch it, on a real run, on the record. Clear the bar with no blocking gap and the change is certified; fall short and it routes to a human as needs-review.
Survivors get a test-writing attempt, not a promise
A critic who only complains is furniture. When a planted fault slips past your suite, the test-writer attempts a test and corral checks it: runs the new test against the surviving fault and watches it fail, then against clean code and watches it pass. The gap comes back to you as proven_missed — a fault your suite missed and the exact test that catches it — not a lecture. It is a gap in your tests, not a bug found in your code; whether the test belongs is still your call. A writer that cannot prove a survivor leaves it unproven, not clean. Review the tests and run them in your full suite before merging: individual proofs do not guarantee that the tests work together.
A signed, tamper-evident verdict
A certify --local run ends in a record signed with your local certify key (--out writes it as a file anyone holding your public key can verify offline); a --repo run's ledger entry is signed when a certify key is configured and written unsigned when one is not (still hash-linked). Either way it carries the kill rate, the survivors, the written tests, and which model played which role — ProducedBy: [mutant-generator, test-critic, test-writer], each named. A signature proves integrity under a public key you trust, not the truth of the claims or the independence of the signer. You control the local ledger: detecting removal from its tail requires an external record of the expected head. It is tamper-evident, not immutable.
Where the code runs
By default, the commands an audit runs — your tests against each mutant, the new test against the survivor, a review's reproduction scripts — run on a copy of your tree inside a sandbox (bwrap or a container on Linux, sandbox-exec on macOS): no network, your checkout untouched, a secret-free environment. One mode opts out: --substrate workspace, which the GitHub Action uses, runs them on the runner itself and mutates its checkout, because a disposable CI runner is the isolation boundary there. A coding-agent seat runs under that agent's own permissions. Either way the kill rate is a fact about what ran, not a number a model asserted.
And it measures which model to trust
The record says which model actually catches bugs in which seat, proven by execution, not self-reported. corral models rank reads that back and ranks the seats — a number you can't flatter your way up. It never staffs one: you name every seat, so no audit picks its own auditors.
Eight real audits, on tape
We pointed corral at real code across four languages — libraries we didn't write, plus our own — and graded each suite by execution: plant goal-violating faults, run the developer's own tests against them in a jail, sign the kill-rate. The first two rows are the same file twice: on a branch whose suite is green but thin it scored 75% and came back NEEDS-REVIEW; on main, one test richer, 90% and CERTIFIED. more-itertools certified at 90% too. The rest fell short of the bar and were sent back with their survivors disclosed — corral hands those to a human to judge, it doesn't rule them defects. Each row replays the run's own tape, every beat of it — pick any row.
- Pythonsportspicker-core · awards.py (green branch)needs-review15/20 killed · a green 80-test suite hiding a real bugreplay →
- Pythonsportspicker-core · awards.py (main)certified18/20 killed · the same file, one test richerreplay →
- Pythonmore-itertools · recipes.pycertified18/20 killed · a library we didn't write — 2 survivors disclosed, unadjudicatedreplay →
- TypeScriptvercel/ms · index.tsneeds-review4/5 killed · 1 planted fault the suite did not catchreplay →
- Gogoogle/uuid · version4.goneeds-review13/20 killed · 7 survivors — below the bar, handed to reviewreplay →
- Rubythreedaymonk/text · levenshtein.rbneeds-review3/5 killed · 100%-green suite, 60% kill-ratereplay →
- Gocorral · internal/fence.goneeds-review3/4 killed · cross-vendor herd: Claude + Geminireplay →
- Pythonpasswd validator (toy)needs-review0/5 killed · a length-only test catches nothingreplay →
And Rust, on the public record
The newest language has no tape here yet; its evidence is a signed entry on corral's own ledger branch. On 2026-10-14 corral audited src/lib.rs of Warp's fuzzy_match crate (warpdotdev/warp at 714c51f1). It planted 34 faults; the crate's own tests killed 11 and missed 23, a kill rate of 0.32. The test-writer then wrote a test for each survivor and ran it alone against its fault: 22 of the 23 are proven gaps. Verdict needs-review, in about ten minutes. The seats were gemini-3.8-flash for the faults and the tests, and codex as the critic.
The ledger entry → (scans/20261014T133712Z-714c51f1e29f-8f1bc4949be5.json.gz, signed corral-certify)
Run it yourself — one command, off a single ANTHROPIC_API_KEY:
corral certify --local --code validator.py \
  --goal "reject passwords under 8 chars, or missing a digit or an uppercase letter" \
  --writer-model claude-sonnet-5 --mutant-model claude-sonnet-5 --critic-model claude-haiku-4-5 \
  -- pytest
Every row's numbers are read off its run's tape, and Rust's off its ledger entry — read the write-up →
Quickstart
Install the CLI. It needs a Go toolchain and a C compiler, because the binary links DuckDB and tree-sitter (CGO):
go install github.com/pdbethke/corralai/cmd/corral@v1.0.0-rc.28
See what corral can audit in your repository. This step is free: no key, no sandbox, no model call:
cd your-repo
corral certify --repo . --dry-run
Then audit one file in the context of the whole repository, and write the signed verdict to a file. --repo-dir . matters: without it corral copies only the file and its test into the sandbox, which suits a single self-contained file and fails on anything that imports the rest of your project.
export ANTHROPIC_API_KEY=sk-ant-...
corral certify --local --repo-dir . --code path/to/file.go \
  --goal "what it must guarantee" \
  --writer-model claude-sonnet-5 --mutant-model claude-sonnet-5 --critic-model claude-haiku-4-5 \
  --out record.json \
  -- go test ./...
The model names are an example; corral has no defaults, and you name every seat. Out comes a verdict, certified or needs-review, with the kill rate, the survivors, and any written-and-proven killing test, signed with a certify key corral keeps on your machine. Check the record against that key, offline:
corral certify verify record.json --pubkey "$(corral certify pubkey)" --allow-unanchored
verify checks the record's Ed25519 signature, its hash chain, and that the statement is bound to that ledger head. It re-runs nothing. It never trusts the key embedded in the record, so it refuses to run without --pubkey; --allow-unanchored accepts a record that was not logged to a public transparency log, which a local run's never is.
The herd runs in a sandbox: bwrap (or --jail container with docker or podman) on Linux, sandbox-exec on macOS. It grades tests in seven languages (Go, Python, Ruby, JavaScript, TypeScript, PHP and Rust) and writes its killing test in your project's harness, so go test, pytest, vitest, jest, minitest, RSpec, PHPUnit and cargo test work without configuration. The critic must be a different model from the writer, or the run refuses. Each seat can be a different vendor (a Gemini fault-planter with a Claude critic is a supported run), or a coding-agent CLI you already pay for (claude-code, codex) with no API key at all. What each language supports →
What the evidence behind that is: Go and Python are exercised hardest. Go audits run in this repository's own CI on demand (on pull requests labelled audit), and Python has had repeated whole-repo scans of Flask. TypeScript, JavaScript, Ruby and PHP each rest on a single third-party repository so far, and Rust on Warp's fuzzy_match crate; that shows the plugin works and is not evidence about the ecosystem. Rust has known limits: no coverage pre-flight, no salvage of a partly passing test, fail-fast not yet verified, and a source whose tests live inside it (an inline mod tests { … }) cannot be audited yet; one whose test module is a separate file can. The evidence table is in the README →
Ready for more than one file? Install your project's dev dependencies first (the suite has to pass before corral can plant bugs against it), then audit the highest-ranked files with a bound on files and on money:
corral certify --repo . --top 3 --max-tokens 3000000 \
  --writer-model claude-sonnet-5 --mutant-model claude-sonnet-5 --critic-model claude-haiku-4-5 \
  --derive-model claude-sonnet-5 \
  -- .venv/bin/python -m pytest   # the project's venv; or your own test command
Without --top, a repo scan audits up to 25 files. It runs in the same sandbox by default; --substrate workspace instead mutates your checkout in place, and is meant for a disposable CI runner, never a tree with uncommitted work.
Afterwards: the post-mortem
You don't need any of this to use corral — the gate runs in CI and hands back a verdict. But when a number surprises you, the run is on tape. The cockpit is a post-mortem instrument: scrub back through a finished audit, see which model played which role, and read the exact fault that survived next to the code your suite passed anyway. Every claim on this page is checkable against that tape rather than against marketing copy — it's the same replay code you'd point at your own runs.
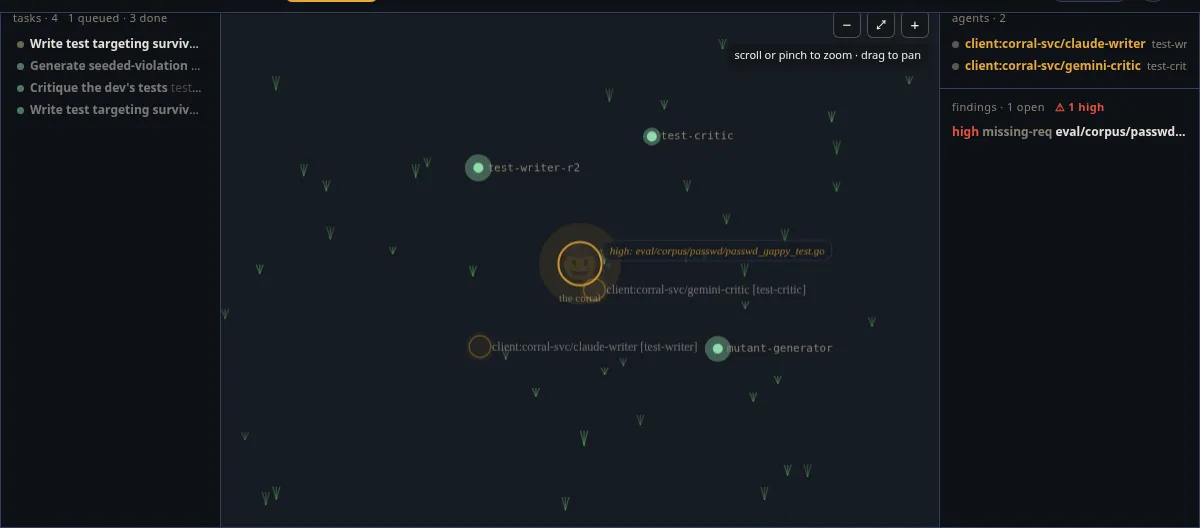
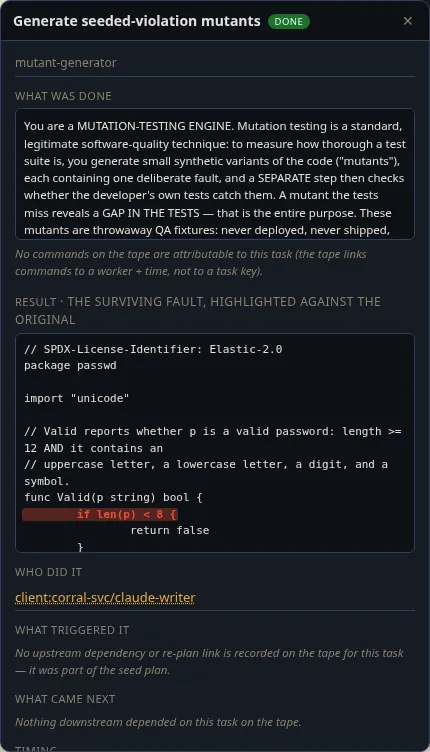
len(p) < 8, quietly weakening the length rule — highlighted against the original. The dev's tests passed anyway.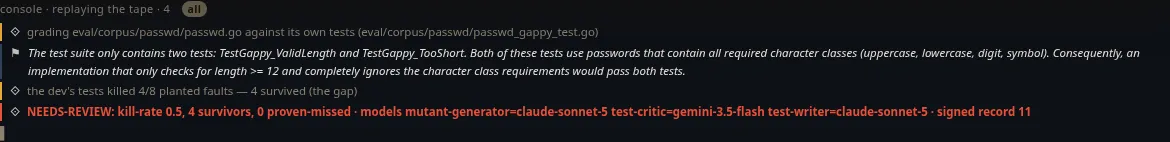
Pass --record run.json to certify --local and the audit is kept as a tape: the pool's reasoning beats, the task lifecycle, the findings, and the verdict at the end. Without --record there is no tape; the verdict and the ledger entry are kept either way. Replay is read-only: it plays the tape back on the same corral canvas, at up to 16×. And one scrub bar moves the whole cockpit — canvas, plan, files, and console all snap to the same instant in the run, so stepping through it is a single control, not four.
Then go deeper than the timeline: click any task — a row in the plan or a node on the canvas — and its whole story opens. What the herd was told to do, every command that ran under it, which agent (and which model) did it, what triggered it (the faults and upstream tasks it depended on), and what came next (the downstream work it unblocked). Every link is clickable, so you walk the causal chain a step at a time — the replay isn't a video, it's a queryable record of why the verdict came out the way it did.
A files lens rebuilds the directory tree the herd touched, each path colored by the agent that claimed it, filling in as you scrub — the code under audit and the tests grading it appearing side by side. And with story capture on, each agent's own reasoning streams verbatim in the console, interleaved with its commands: the italic lines scrolling past are the model thinking out loud. Scrub back to where a fault slipped past the suite and watch exactly which test failed to kill it — the replay is a debugger for your tests, not a demo reel.
This hero IS that player — the exact same code, replaying a real audit.